Acceptance testing with evidence

Revisore

compliance and traceability

One verdict per requirement, on every ticket. Traced to tests on the real product, in a dated, signed report, ready for the EU AI Act file.

Skip the QA team. Keep the expert.

QA TEAM

  • Hire, brief, manage
  • Hand-written tests
budget

ONE EXPERT WITH REVISORE

  • Knows the domain, signs off features
  • Agents write and run tests
same budget

No hiring, briefing or managing: one domain expert signs off, and agents write and run the tests.

Evidence for compliance and regulators

EVIDENCE BY HAND

  • Screenshots and spreadsheets
  • Assembled before the audit
  • Requirements not linked to results
before the audit

EVIDENCE FROM REVISORE

  • Dated, signed report per run
  • Every requirement traced, gaps too
  • Every call and verdict recorded
on every ticket

What was tested, against what, with what result, signed. Compliance stays with the provider.

What is Revisore

An agentic harness for acceptance testing

Understands

The ticket and its discussion.

Writes

Requirements, then tests.

Runs

On the real product.

Traces

Requirement to test to result.

Proves

A dated, signed report.

Who it's for

You don't write tests. You judge them.

Test engineer

Reviews tests, not writes them.

Technical product manager

Judges each verdict.

Compliance officer

Gets AI Act evidence.

The problem

Repeatable. Consistent. Proven.

Same process, every ticket

Testing depends on who had time. Hand-written suites drift.

Evidence, not a green build

Customers and regulators want to see what was tested, and the result.

Evidence-proven solution instead of a guess

An AI answer is a probability, not a fact, and it can't prove itself. Evidence of what actually ran can.

The solution

Agents held to your requirements

Agents work; code, not a model, checks every step. Red is repaired and rechecked. Only green moves on.

tracedone verdict per requirementTicketand discussionRequirementsfrom the ticketTestsfrom requirementsRunon the real productResultsone per testReportbugs, evidenceVerdictper requirementgate: code checks every steptraced: requirement to test to result Ticketand its discussionRequirementswritten from the ticketTestswritten from the requirementsRunon the real productResultsone per testReportbugs and evidenceVerdictone per requirementgate: code checks every steptraced: requirement to test to result

What the code checks

Rules with a testable result

Rejected: always-true assertions, empty data, totals-only comparisons. 119 rules, each checked on evidence. A changed check needs approval.

What a person still judges

Whether testing was good enough

Green means checks passed, not good coverage. A person approves the design, reviews the PR and judges each failure.

What a testing run produces

From the testing flows. Requirements analysis stops earlier.
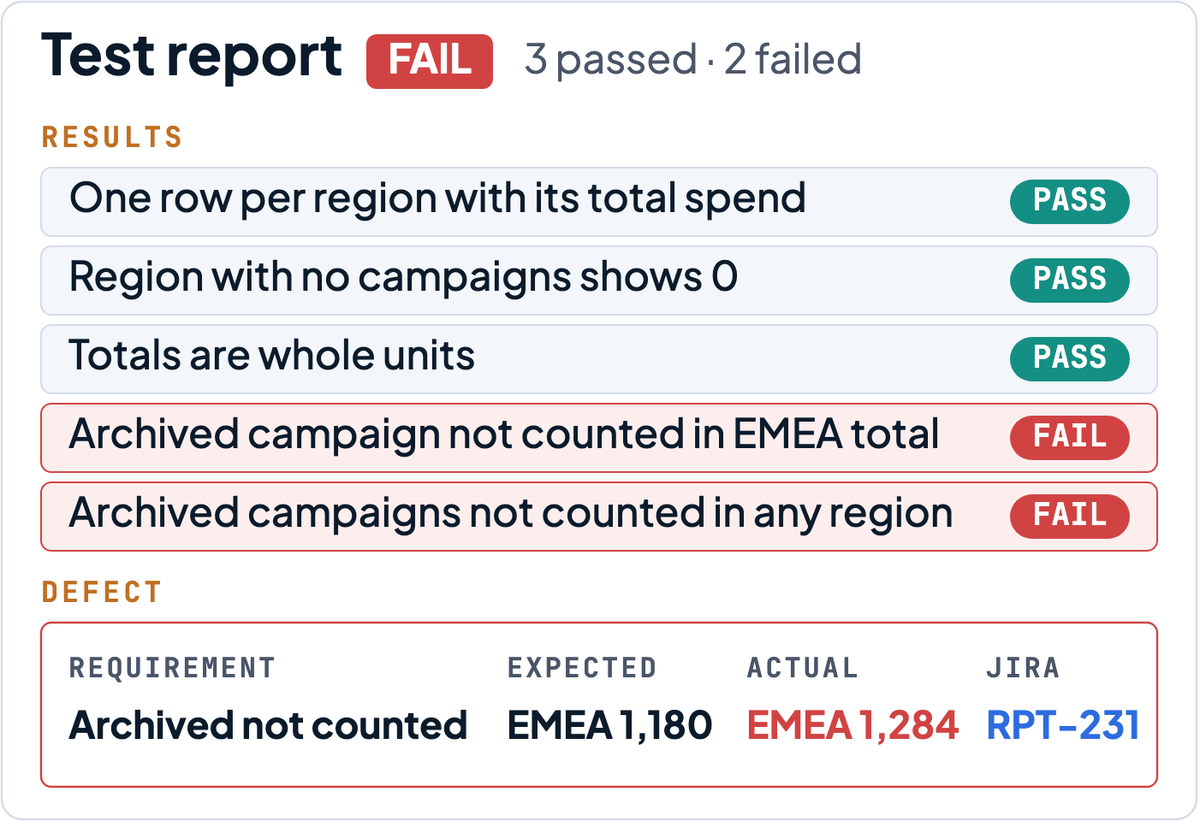
A test report marked FAIL with three passed and two failed scenarios, and one defect showing the expected value, the actual value and its Jira link.
The test report. Open full size
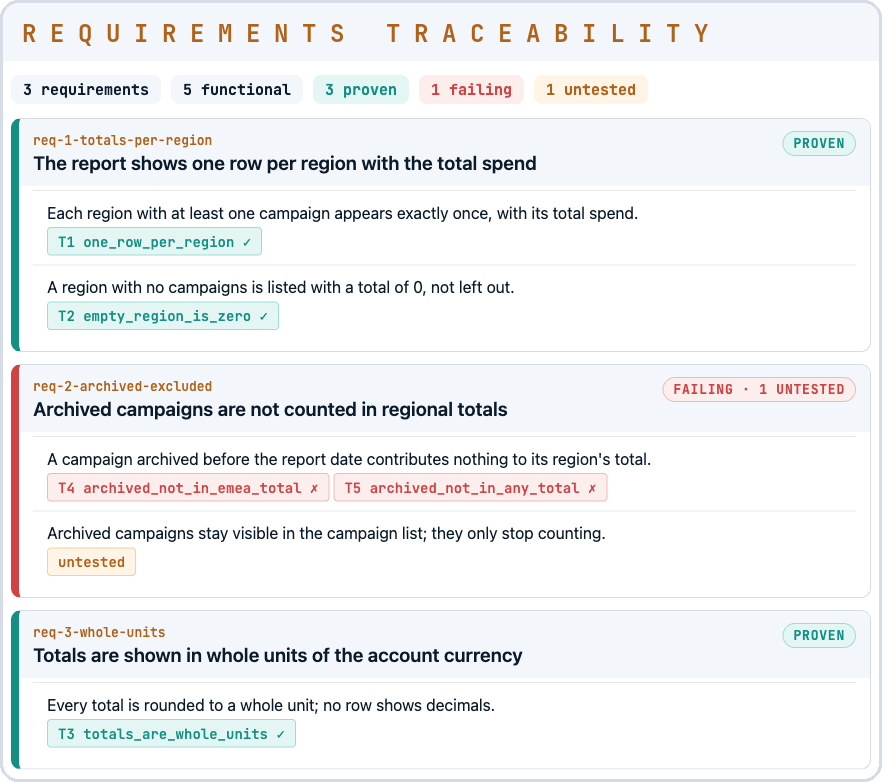
Requirements traceability: each requirement with the tests that prove it, a failing requirement in red, and one requirement no test covers yet.
Requirements traceability. Open full size

Defects

Expected against actual

linked to Jira

Evidence

Dated and kept

for the technical file

Request a ticket walkthrough

How it works

4 chapters, used as needed

  1. Input ticket, question or anomaly
  2. 1 Introduction code map · plan · environment
  3. gate
  4. 2 Requirements from the ticket
  5. gate
  6. 3 Testing written and run
  7. gate
  8. 4 Reporting bugs · report · test-code PR
  9. gate
  10. Verdict per requirement, for you

Outside the run a watchdog limits time, turns and money.

Chapters per flow

FlowStarts from1 Introduction2 Requirements3 Testing4 Reporting
Ad-hoc checka questionyesnoyesyes
Bug reporteran anomalyyesnonoyes
Requirements analysisa ticket in designyesyesno code yetno
Happy-path testera ticketyescriteria, approved by a personyesyes
Functional testera ticketyesyesyesyes
Data testera ticketyesyesyes, row by rowyes
Performance testera releasein progress
AI testeran AI featurein progress

Test flows

8 test flows, one harness

FLOW 1 OF 8

Ad-hoc check

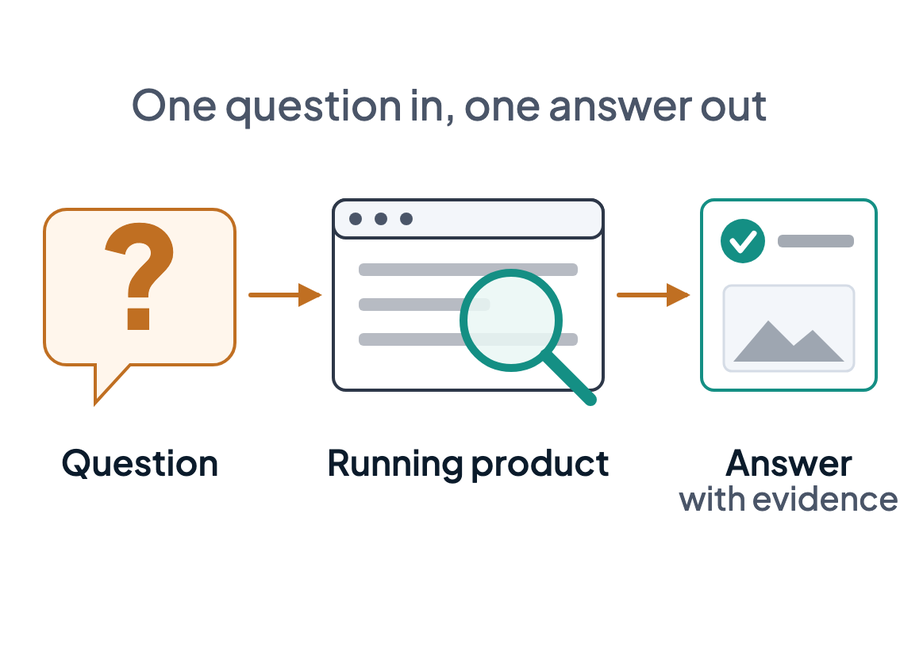
One question, no ticket.

  • An answer from the product
  • Its evidence
A question goes to the running product and comes back as an answer with evidence.

FLOW 2 OF 8

Bug reporter

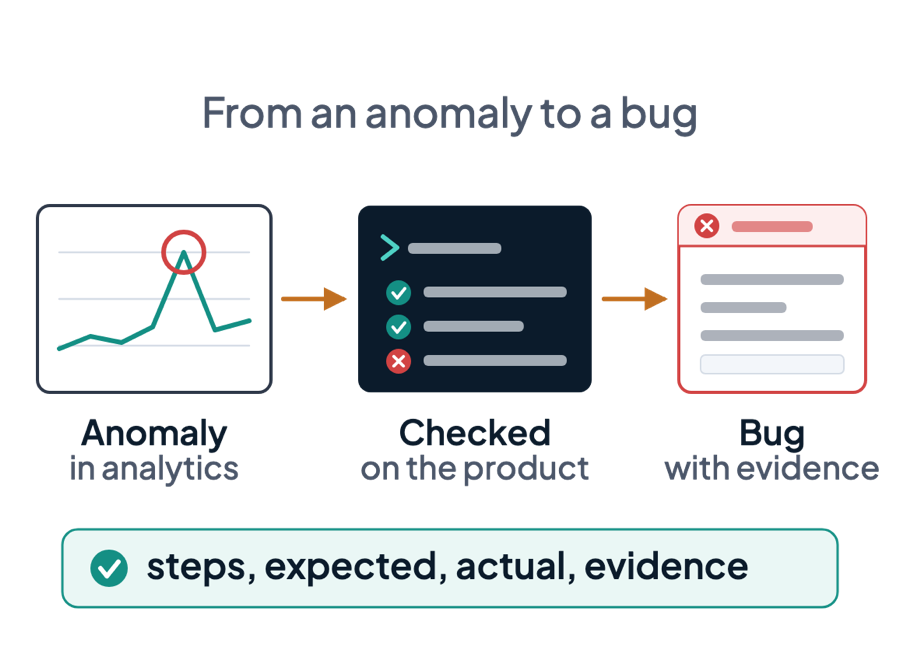
An anomaly in analytics.

  • Checked on the product
  • Repro steps, expected vs actual
  • A bug with evidence
An anomaly in analytics is checked on the running product and becomes a bug with steps to reproduce, expected and actual, and evidence.

FLOW 3 OF 8

Requirements analysis

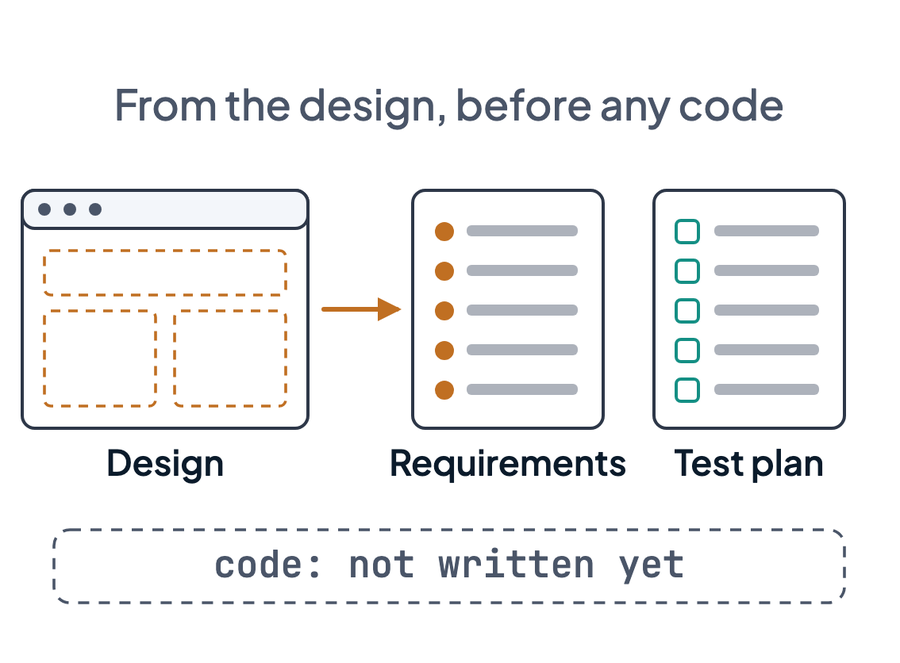
Ticket in design, no code yet.

  • All requirements
  • A test plan
  • Before any code
A design turned into requirements and a test plan, with the code not written yet.

FLOW 4 OF 8

Happy-path tester

Every criterion checked, fast.

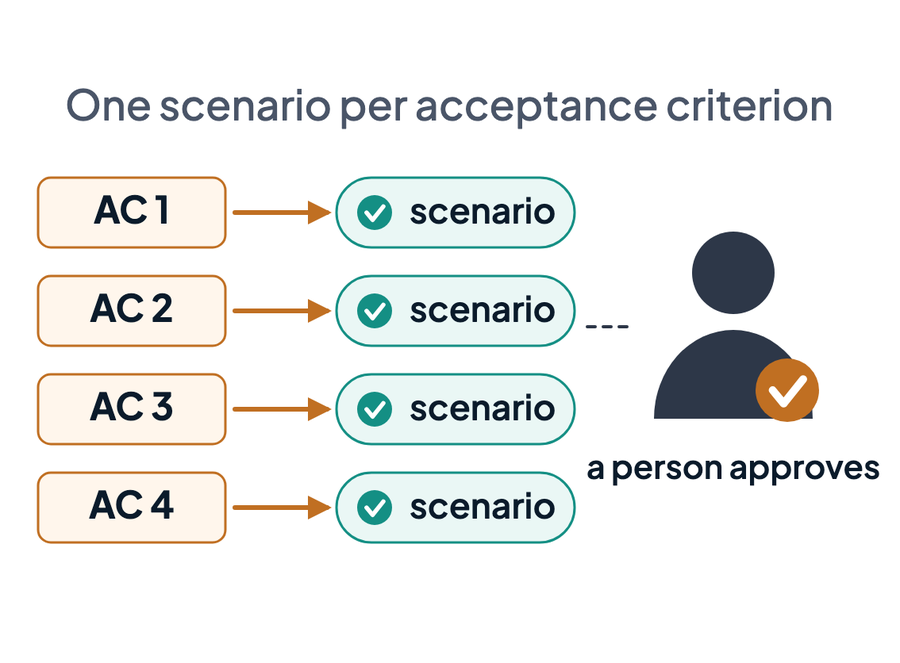
  • One scenario per criterion
  • A person approves
Four acceptance criteria, each with one scenario, and a person who approves.

FLOW 5 OF 8

Functional tester

A ticket needs full coverage.

  • Requirements
  • Bugs
  • Tests
  • A report
  • A run on the branch
  • A test-code PR
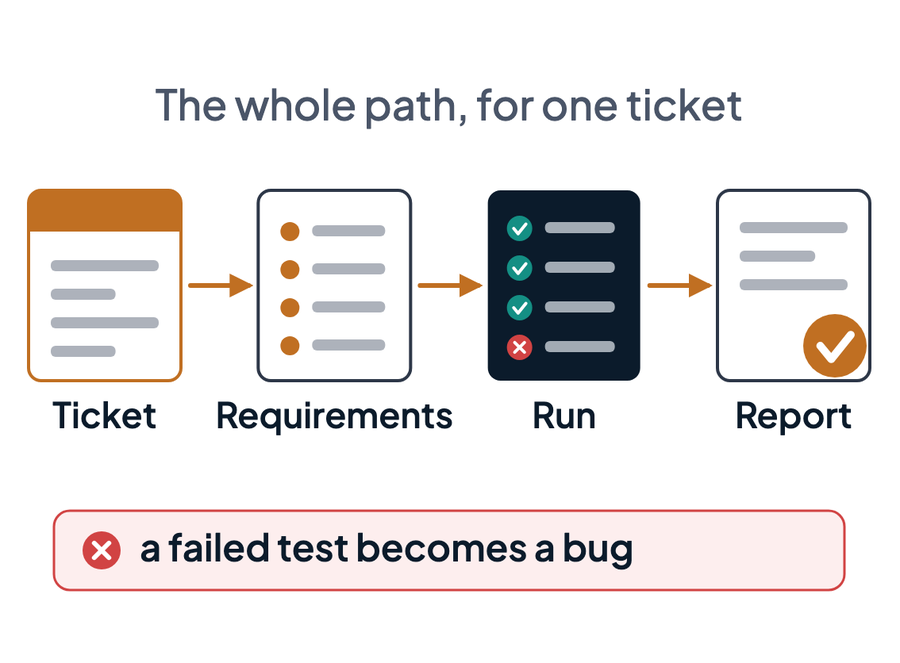
A ticket becomes requirements, then a run, then a report; a failed test becomes a bug.

FLOW 6 OF 8

Data tester

A metric, report or pipeline changes.

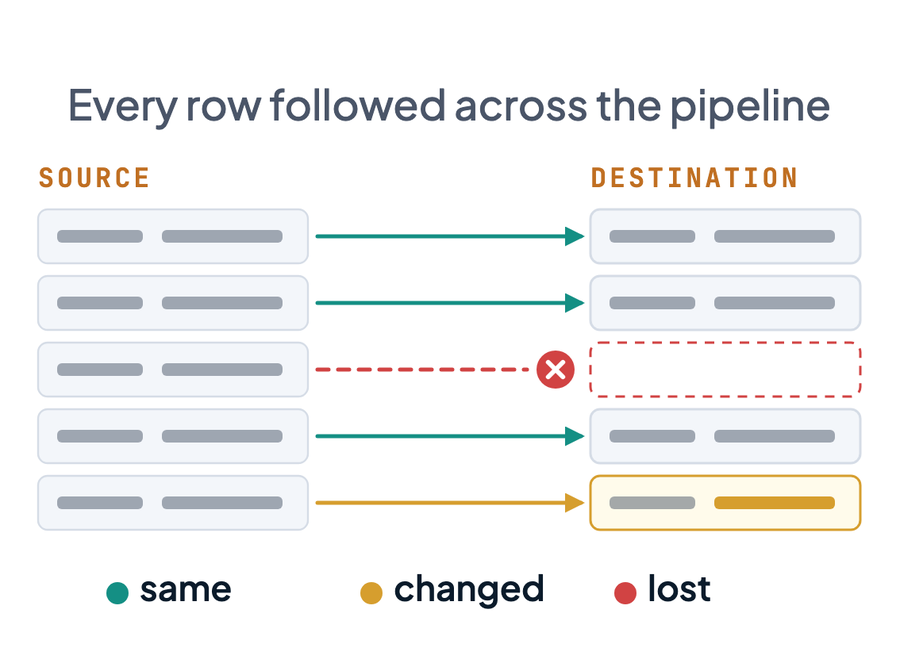
  • Every row traced
  • Lost rows named
Rows followed from a source table to a destination table: most arrive the same, one is changed, one is lost.

FLOW 7 OF 8 IN PROGRESS

Performance tester

A release has to hold up under load.

  • Response times under load
  • Evidence for sign-off
The product under load Load Evidence IN PROGRESS

FLOW 8 OF 8 IN PROGRESS

AI tester

Your product has an AI feature: a model, a chatbot or an agent.

  • The AI feature tested against its requirements
  • Evidence for the AI Act file
Testing the AI itself AI feature Evidence IN PROGRESS

What it is

EU law for AI, by risk

Regulation (EU) 2024/1689. Higher risk, more proof.

Who it applies to

AI used in the EU

Providers and deployers, wherever based.

Where it fits

WHAT THE ACT ASKS OF THE PROVIDER

WHAT REVISORE CONTRIBUTES

Pre-set test metricsArt. 9(8)
Criteria fixed before runs
Test and validation proceduresArt. 17(1)(d)
One flow, every ticket
Dated, signed test reportsAnnex IV 2(g)
Report and traceability per run
Records kept 10 yearsArt. 18
Ready to file

High-risk AI only. Revisore supplies evidence; the provider owns compliance and the 10-year retention policy (Art. 18).

When it applies

  1. New deadlines in forceReg. (EU) 2026/1744
  2. High-risk AI systemsHiring, credit, education, essential services
  3. AI in regulated productsMachinery, medical devices, vehicles

AI governance

Every agent watched, every step on record

Governance sits outside the agents: isolated runs, code checks, a full record.
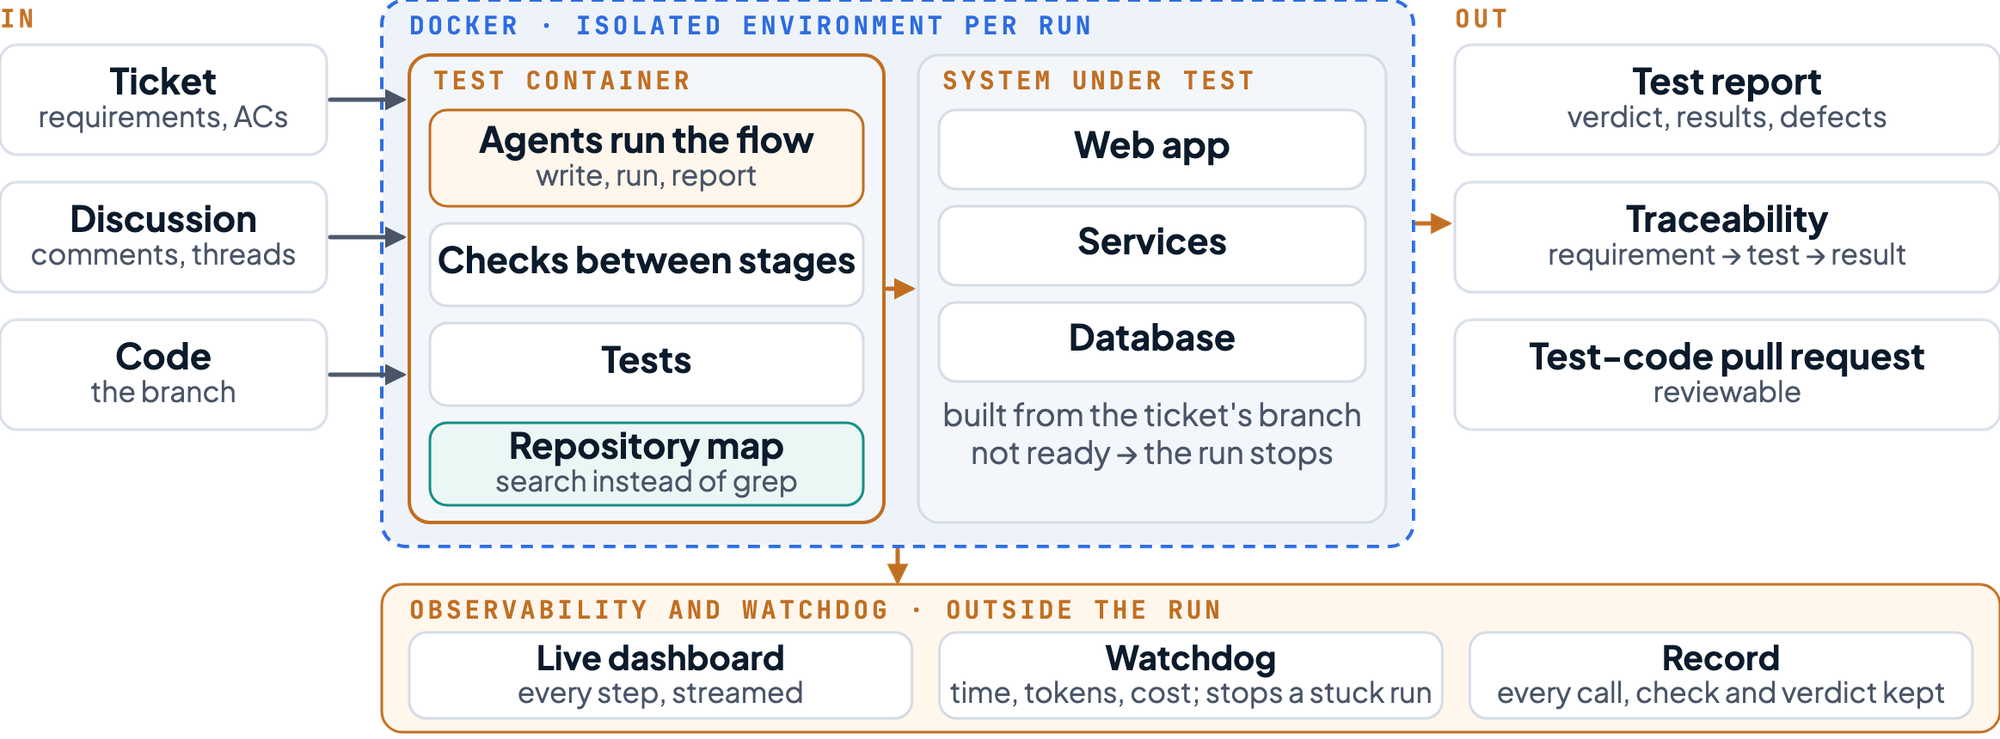
Architecture. In: the ticket, its discussion and the code branch. Inside an isolated Docker environment per run: a test container where agents run the flow, with checks between stages, tests and a repository map, next to the system under test built from the ticket's branch. Out: a test report, traceability and a test-code pull request. Observability and the watchdog sit outside the run.

Every step passes a gate

Agentdoes the work Rule gatecode checks the result Next steponly when green Repair agentfixes what the gate found green red checked again Agentdoes the work Rule gatecode checks the result Repair agentfixes what it found Next steponly when green red again green

Most first attempts fail the gate

59%red on the first check858 of 1,446 steps
235red first, green at the endfixed by the repair agent
8.8 smedian time for one gatecode, not a model

235 of 858 red steps were fixed by the repair agent, no person involved. The other 623 stopped the run and went to a person.

2,079 checks in 206 runs, 21 Aug to 5 Oct 2026. Later rounds hold only harder cases. Model spend over 28 runs: median $18, mean $34, plus review time.

What it runs on

Models
Dynamic
chosen per phase
Orchestrator
Go · gRPC
polls Jira, runs, streams steps
UI
Go + plain JS
dashboard: runs, cost, verdicts
Tests
In a container
next to the product, isolated
Search
Keyword + semantic, re-ranked
local CPU, no vector DB
Watchdog
Go · SQLite
limits, budgets, the record
Configs
JSON flows · Markdown agents · YAML limits
rules in git
Infrastructure
Docker Compose
one environment per run

One production run: a 212-token pointer replaced a 64,000-token map on every turn. Per-turn context, not run total. Open source: where-are-we.

Working with us

Run by us, or by you

Managed by Chiron Systems

We host it. Data is processed by us and our model provider.

In your environment

Your servers, your model endpoint. A self-hosted model keeps data with you; an external one has its own terms.

What it needs

Tracker and repo access, and an environment to run the product.

Pricing

Per engagement, from scope and ticket volume.

The demo: one ticket, from requirements to evidence.

Request a ticket walkthrough

Get in touch

Nikita Gavrish · Evaluation Engineer · Chiron Systems